

00no account needed
Titanic EDA and models
The starting point: data cleaning, feature engineering and eight classifiers compared by accuracy.
Five runnable notebooks that take one dataset from a Kaggle starting point to monitored, versioned models, and an image example.
Five notebooks take the Titanic passenger list from a Kaggle starting point to monitored, versioned models, with their outputs committed. Each runs in about a minute; notebooks 01 to 04 need a free account.
The starting point: data cleaning, feature engineering and eight classifiers compared by accuracy.
Why one passenger died, which ticket would have saved him, two models that disagree, and what the forest learned overall.
Two weeks of traffic with a shadow model, then a feed that sends fares in pence, caught by drift detection and named by an explanation.
Error analysis with explanations, better features, then v2 shipped as a new version and compared with v1.
XGBoost, explained with its own TreeSHAP values and through a scoring endpoint that Kaimei calls.
A MobileNetV2 classifier uploaded with its photos attached, then asked why on new pictures. Each answer is drawn exactly as the dashboard draws it.
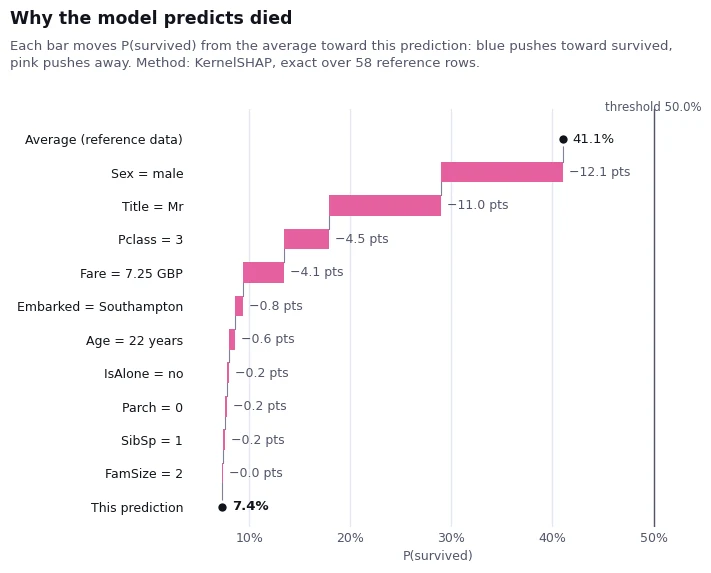
kaimei.tabular.plot_explanation.